LoopAhead: Speculating Ahead for Faster Decoding in Looped Language Models
LoopAhead: Speculating Ahead for Faster Decoding in Looped Language Models
Zixuan Liu, Nan Xue, Rui Bao, Yuhang Xu, Xiaofeng Cao, Jiangchao Yao, Zhiyong Chen
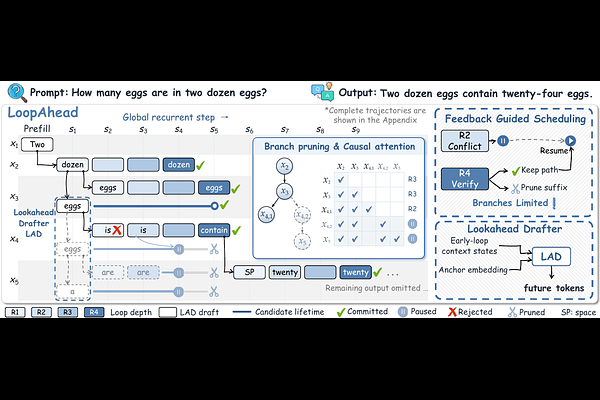
AbstractLooped Transformers improve parameter efficiency by repeatedly applying the same Transformer layers. However, generating each token still involves sequential computation and repeated access to model weights, leading to high decoding latency. Recent pipelined self-speculative decoding methods reduce this delay by drafting tokens from early-loop predictions and asynchronously advancing tokens at different recurrent depths in the same batch, but they do not fully exploit early-loop features for longer lookahead and still spend computation verifying incorrect speculative branches. We introduce \method, a speculative decoding framework for looped transformers that enables earlier drafting of future tokens and assigns complementary roles to different recurrent depths. A lightweight lookahead drafter (LAD) predicts multiple future tokens with early-loop states, and deeper-loop feedback helps decide which draft branches to continue and which to pause, while the full-depth model makes the final token decisions. LoopAhead achieves up to 7.82x decoding speedup over autoregressive decoding while preserving the target model's output distribution.