Gradient Boosting with Kolmogorov-Arnold Units for Interpretable Regression beyond Pairwise Interactions
Gradient Boosting with Kolmogorov-Arnold Units for Interpretable Regression beyond Pairwise Interactions
Minjong Cheon, Hanseon Joo, Eunji Lee
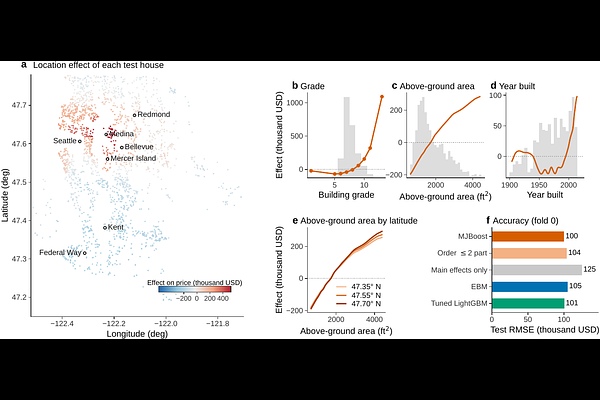
AbstractInterpretable models for tabular regression, such as the explainable boosting machine (EBM), restrict a prediction to main effects and pairwise interactions so that every part of it can be plotted. When the target depends on three or more inputs jointly, this restriction costs accuracy, and a black-box model with post hoc explanations becomes the usual fallback. Here we present MJBoost, a gradient boosting method whose weak learner is a single Kolmogorov-Arnold unit $g(\sum_p φ_p(x_p))$ with penalized spline inner and outer functions. Each unit is fitted in closed form by alternating penalized least squares, starting from principal Hessian directions of the residual, and categorical and missing inputs enter the units directly. Because a unit depends on each input only through one inner function, the fitted model has an exact functional ANOVA decomposition into main effects, pair effects and a higher-order remainder, which one-dimensional convolutions compute. On synthetic targets of interaction order three to six, the test error of MJBoost is up to 13 times lower than that of EBM, and its decomposition recovers the true variance share of every order to within 0.04. On the 35 regression tasks of the OpenML-CTR23 benchmark, it has a lower test RMSE than EBM on 21 tasks and a higher one on 2 (geometric-mean RMSE -29.1%). On these tasks the main and pair effects of the fitted model explain a median 0.992 of its variance, so the model reads as plots where the data allow, and the decomposition measures the higher-order part where they do not. With Newton steps the same algorithm classifies: on 32 binary tasks of OpenML-CC18 its test log-loss is on par with that of EBM, and on 11 multiclass tasks its mean log-loss is lower than that of EBM on 8 and than that of tuned LightGBM on 7.